
This AI content pipeline case study covers a system we built for ourselves. Ranbanka Systems (our own in-house AI system) plans, writes and checks long-form articles for the Ranbanka blog, then stops and waits for a person to approve each one before it goes live. We built it and run it on www.ranbanka.com, and it is a working example of the kind of AI system we build for clients.
The challenge
In April 2026, an audit of our own website showed a clear gap: we had no blog, and so almost no organic search traffic. The fix was obvious, but the work was not. Long-form, expert articles take a lot of time to research and write well.
Using AI to write them brought a different problem. AI-written content has a well-known risk: it invents things. For a company website, that means made-up claims about clients, results and numbers. We can never publish those. An invented statistic or a client we never worked with would damage trust with exactly the buyers we want to reach.
So the real requirement was not "generate articles". It was: make AI content trustworthy enough to publish under our own name, without giving up human control.
What we built
We built a content pipeline in LangGraph. Each article moves through a fixed set of steps, and each step has one job.
Duplicate check before any AI call
The first step, check_duplicate, runs before any language model is called. If a published post or a draft already in review targets the same keyword, the run stops. This avoids keyword cannibalization, where two of our own pages compete for the same search, and it means no model call is spent on a draft we would not use.
Research and outline
research_outline plans the sections and the search intent behind the keyword. It also picks real portfolio proof points, a blog category, and up to three related published articles to link. Proof points come from our actual delivered work, not from the model's imagination.
Drafting and revision
draft_article writes the article. When a draft comes back for revision, the same step fixes every fact, SEO and editor note raised against it, so each revision addresses the full list rather than a part of it.
Fact check and SEO check, in parallel
Two checks run side by side:
- Fact check: flags any claim about Ranbanka that the site's own data files do not support, and any statistic without a source. The checker may only use our verified data: portfolio, testimonials, clients, services and company stats.
- SEO check: written in plain Python, not AI. It checks title and meta description length, keyword placement, headings, word count and internal links.
Quality gate
If the checks find problems, a quality gate sends the draft back for an automatic rewrite, up to three drafts. After that, the pipeline stops trying and hands the article to a person.
Human review
At human_review, the draft opens in the browser. The editor approves it, asks for a revision, or rejects it. Pipeline state is checkpointed, so review does not have to happen straight away; an editor can come back to a draft days later and pick up where it paused.
Publish
Only after approval does publish write a Markdown file with frontmatter. Our Next.js site builds that file into a static page and adds it to the sitemap. If you are weighing up the framework itself, our guide on Next.js website development explains when static generation makes sense.
Batch mode
For larger content plans, a batch mode drafts many topics, three at a time in parallel. Before any batch starts, a preflight runs that costs nothing.
How we delivered it
The pipeline was built in-house by the Ranbanka team, on a stack chosen for control and traceability:
- Claude Opus 5.5 with prompt caching for planning, drafting and fact checking
- LangGraph with a SQLite checkpointer to orchestrate the steps and save state between them, which is what makes delayed human review possible
- Python for the pipeline and the rule-based SEO checks
- Next.js static generation to turn approved articles into static pages
- Markdown with frontmatter as the hand-off format between the pipeline and the site
The hardest part was trust, and we addressed it with two firm rules. First, the fact checker is limited to the site's own verified data. If a claim about us is not in our portfolio, testimonials, client list, services or stats, it gets flagged. Second, a person approves every article. The automatic rewrites reduce the editor's workload, but they never replace the editor's decision.
The pipeline is also covered by an offline test suite.
The result
- 29 articles published on the Ranbanka blog, each one approved by a person before going live.
- 12 of 12 cases passed in the live fact-checker evaluation.
- A first test article of about 1,900 words was clean on its first draft and took about 90 seconds end to end.
- An offline test suite covers the pipeline.
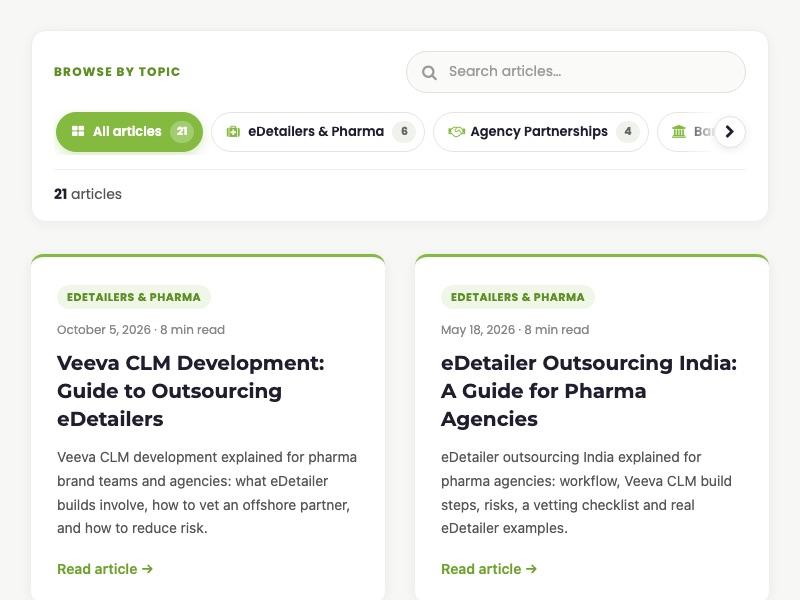
We went from no blog to 21 published long-form articles, each one checked against our own verified data and approved by a person before it went live. The editor now reviews drafts that have already been through fact and SEO checks, rather than starting from a blank page.
The same pattern carries over to client work: a defined sequence of AI steps, checks grounded in your own verified data, rule-based validation where rules are enough, and a human approval point before anything leaves the system. You can see this alongside our other AI builds in our portfolio, and read more about the assistants, automation and AI pilots we offer on our AI solutions page or the full list of services.
Want a system like this for your team?
If your team needs AI that produces work you can actually publish or send, with checks against your own data and a person in control, we would be glad to talk it through. Book a free consultation and we will respond within 24 hours.